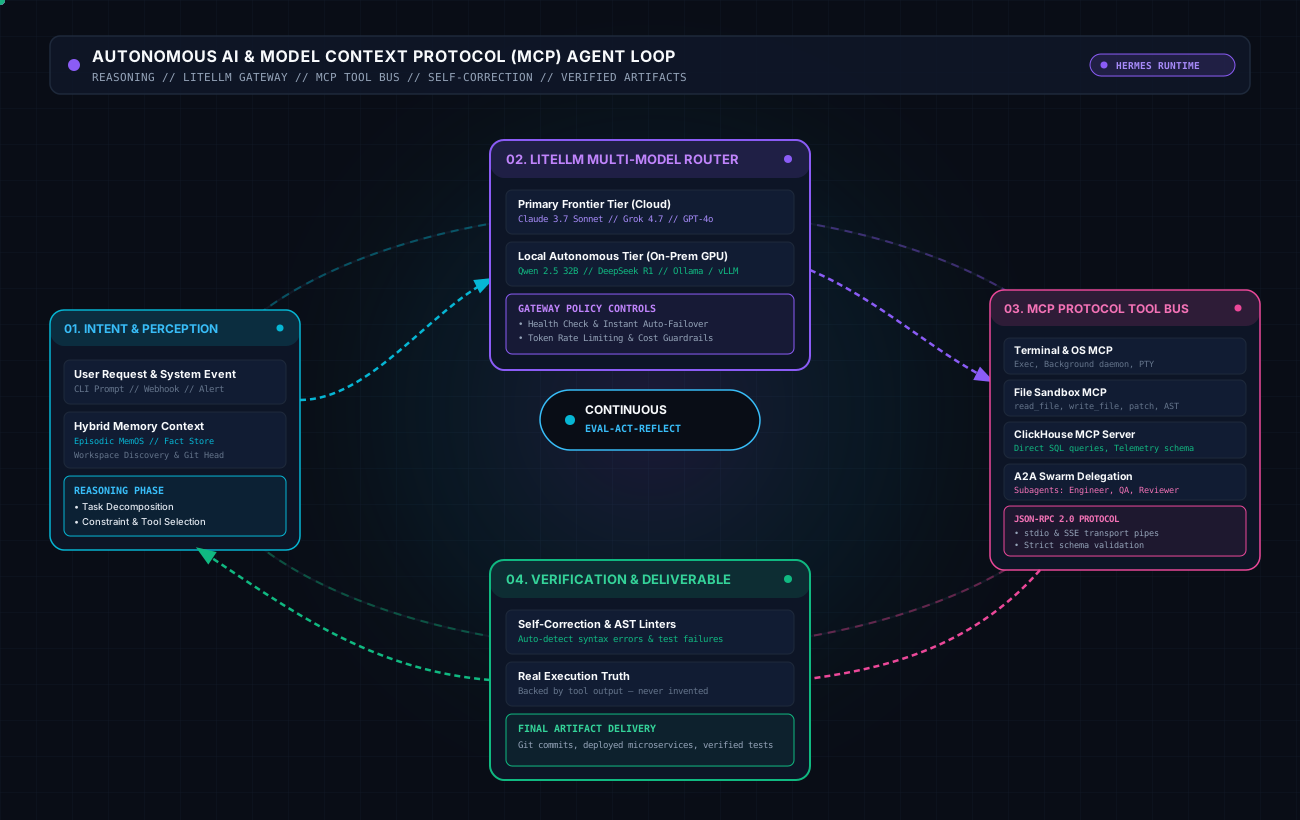
Sovereign AI & Bare-Metal Local Inference Stacks
High-throughput, private LLM serving infrastructure deployed directly on private bare metal to eliminate cloud API egress, token taxation, and confidentiality leaks.
Show detail (3)Hide detail
- GGUF Quantization Precision: Deep experience selecting optimal quantization profiles (IQ4_XS, Q4_K_M, Q5_K_M, Q8_0) balancing perplexity scores against memory bandwidth limits.
- PagedAttention & KV Cache Paging: Tuned vLLM serving parameters (gpu_memory_utilization=0.92, max_num_seqs=256) to maximize token throughput for concurrent agent requests.
- Sub-Second Tool-Calling Models: Championed LiquidAI LFM2-1.2B-Tool-GGUF (1.16 GiB VRAM footprint, 0.24s latency) as the optimal lightweight edge model for instant JSON tool synthesis.